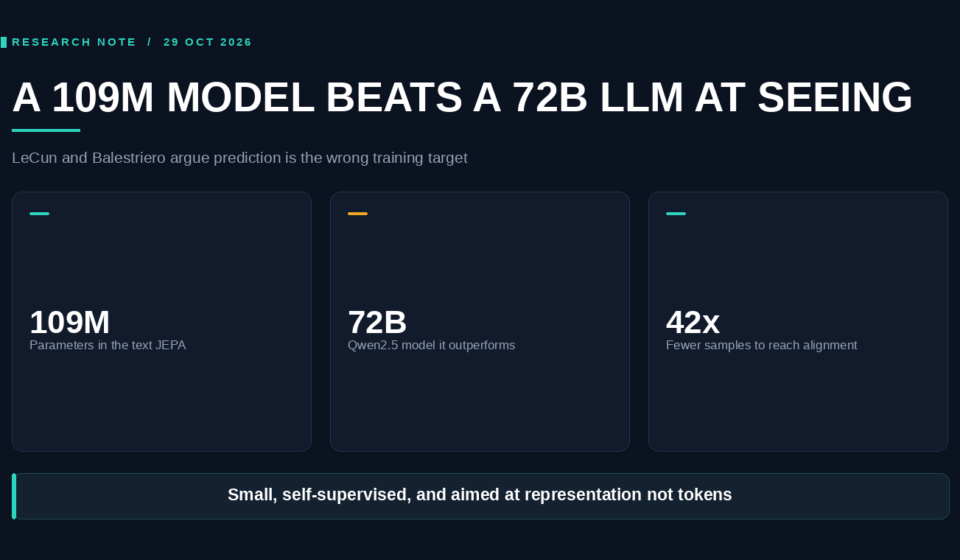
A 109M Model Beats a 72B LLM at Seeing
LeCun and Balestriero argue that predicting the next token is the wrong target, and back it with a model 660 times smaller.
Yann LeCun and Randall Balestriero posted a paper on 29 October 2026 arguing that next-token prediction is a poor objective for learning representations. Their 109-million-parameter text JEPA aligned images and text better than Qwen2.5-72B on their measure, and reached that alignment with 42 times fewer training samples. The work gives the JEPA camp empirical ammunition in a long-running dispute over architecture.