Nvidia Buys Throughput, Not Capacity
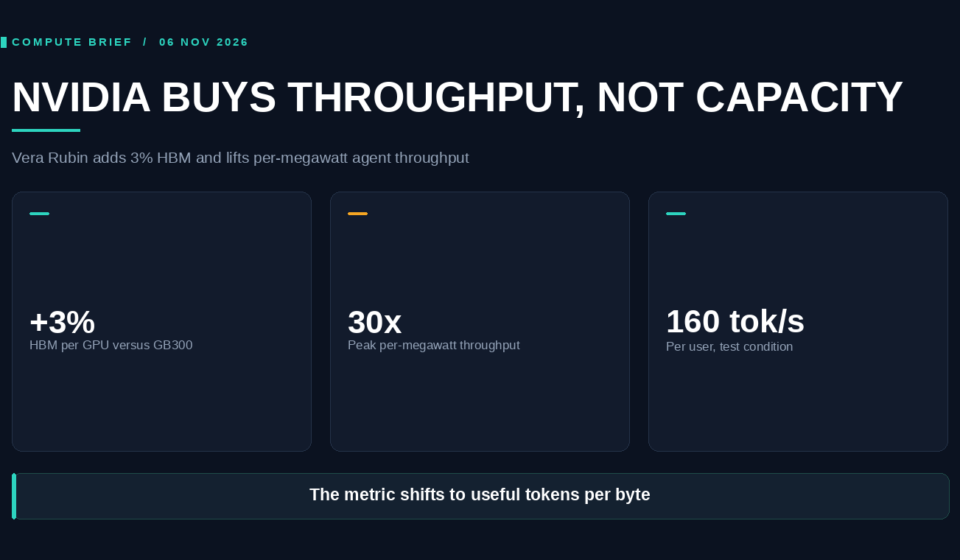
Nvidia is arguing that memory scarcity is answered by system design, not by adding HBM capacity per chip.
Nvidia published a technical note on 5 November 2026 describing full-stack co-design across GPU, CPU, network, storage and software to relieve HBM pressure. Using the SemiAnalysis AgentX benchmark on a DeepSeek V4-Pro workload at 160 tokens per second per user, the company says Vera Rubin NVL72 delivers up to 30 times the per-megawatt agent throughput of GB300 NVL72, while HBM capacity per GPU rises only about 3%, to 288GB. Methods include NVFP4 compression of weights and KV cache, distributing weights across up to 72 GPUs, and offloading inactive context to CPU memory and storage.